Model overview
What is F5 TTS? A clear guide to the speech model
What is F5 TTS? It is a text-to-speech model that uses a short reference recording and written text to produce speech with a similar vocal character, rhythm, and expressive delivery. This guide explains the model in practical terms.
Core workflow
How F5 TTS works
F5 TTS combines a reference voice with target text, then generates speech that follows the reference’s acoustic cues while preserving the requested words.
-
1
Provide reference audio
Choose a clear voice sample with enough spoken content for the model to identify tone, pacing, pronunciation, and other acoustic characteristics.
-
2
Add the target text
Enter the words you want spoken. The text supplies the message, while the reference recording supplies the vocal example that guides the output.
-
3
Generate the speech
F5 TTS aligns the reference and text, then synthesizes an audio result intended to sound coherent, natural, and related to the supplied voice.
Related paths
What F5 TTS can do
These related pages examine the model from practical angles, including its voice behavior, online access, and cloning workflow.
- what is f5 tts voice See how the model’s reference voice shapes tone, pacing, and the character of generated speech.
- f5-tts online Review what an online interface changes compared with running the model through a local setup.
- f5 tts voice cloning Understand how reference-based synthesis relates to voice cloning and where careful usage matters.
Input to output
F5 TTS in practice
The central transformation is simple: a voice reference and written script become a new spoken passage. Quality depends on the recording, text, and generation setup.
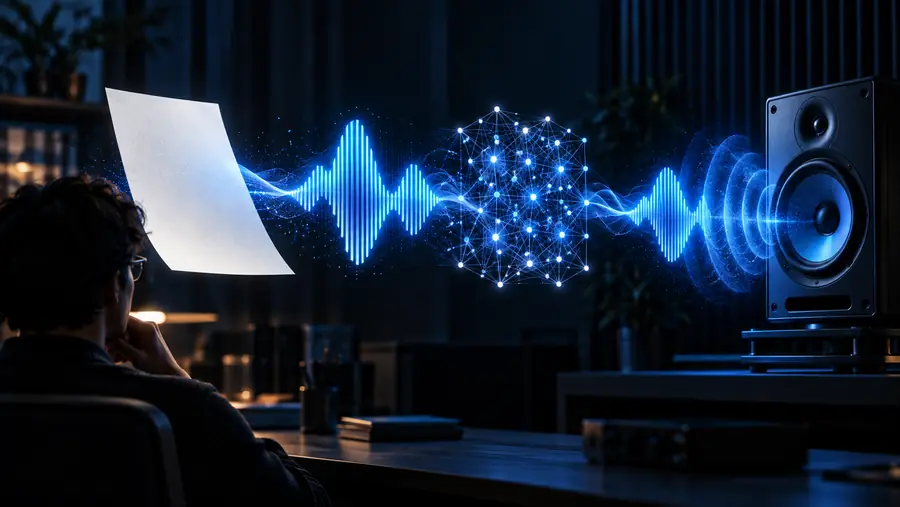
The output follows the reference, not a perfect recording of it.
Reference and scriptGenerated speechA practical comparison
Who uses F5 TTS
F5 TTS is best understood as a reference-guided speech model rather than a universal replacement for every voice workflow.
| F5 TTS workflow | Conventional fixed-voice TTS | |
|---|---|---|
| Voice input | Uses a short reference recording to guide the generated voice | Usually selects from a predefined voice library |
| Text control | Generates speech from the supplied script | Generates speech from the supplied script |
| Voice variety | Can adapt output toward different reference voices | Variety depends on the voices included by the provider |
| Expressive cues | Can reflect aspects of the reference’s timing and delivery | Often follows the style limits of a fixed voice |
| Consistency | May vary with reference quality, text, and settings | Often more predictable within one preset voice |
| Typical users | Creators, researchers, developers, and teams testing voice workflows | Anyone needing straightforward speech from a stable preset |
| Best fit | Reference-based experiments and expressive narration | Routine narration with a known, repeatable voice |
Important caveats
Where F5 TTS has limits
A capable model still needs suitable inputs and responsible handling. These boundaries help set realistic expectations before generating speech.
It cannot guarantee an exact vocal copy
A reference recording guides the result, but generated speech may differ in timbre, pronunciation, emotion, or timing.
What to do instead
Use a clean, relevant reference and compare several outputs rather than expecting a perfect duplicate.
It cannot fix every poor recording
Background noise, overlap, clipping, very short samples, or unclear speech can weaken the reference signal.
What to do instead
Start with a clear recording containing one speaker and minimal environmental noise.
It cannot replace editorial review
The output may mispronounce names, abbreviations, unusual words, or text with ambiguous punctuation.
What to do instead
Listen through the complete result and revise the script or pronunciation-sensitive sections.
It cannot establish permission for a voice
Technical ability does not prove that a person has agreed to the use of their recorded voice.
What to do instead
Use voices with appropriate authorization and label synthetic or reference-guided audio when needed.
Next step
Put the model in context
F5 TTS is easiest to understand by comparing its inputs, workflow, and generated results. Explore the experience through the available product route, then judge whether its reference-based approach fits your narration or voice project.
See what reference-guided speech can sound like
- Start with a clear reference recording
- Use a short script with straightforward punctuation
- Review every generated result before publishing
Common question
F5 TTS FAQ
F5 TTS is a text-to-speech model that generates spoken audio from written text while using a reference recording to guide the voice. It is designed for reference-based speech synthesis rather than choosing only from a fixed list of preset voices.
It is both a trained speech model and part of a text-to-speech workflow. The model processes text together with reference audio to create a new spoken passage with related acoustic characteristics.
No. F5 TTS can use a reference recording to guide vocal character, pacing, and delivery, but results depend on the recording, script, and generation conditions. Similarity should be treated as an output quality goal, not a guarantee.
The basic workflow needs target text and a suitable reference recording. Clear single-speaker audio usually gives the model more useful information than noisy, clipped, overlapping, or very short material.
F5 TTS can be useful to developers, creators, researchers, and teams exploring expressive or reference-guided narration. It is most appropriate when adapting a voice reference matters more than using a standard preset voice.